How we built an M4 Mac mini cluster to cut AI cloud spend by $40k/year
Real-world infrastructure blueprints from a CTO deployed in 20+ countries.
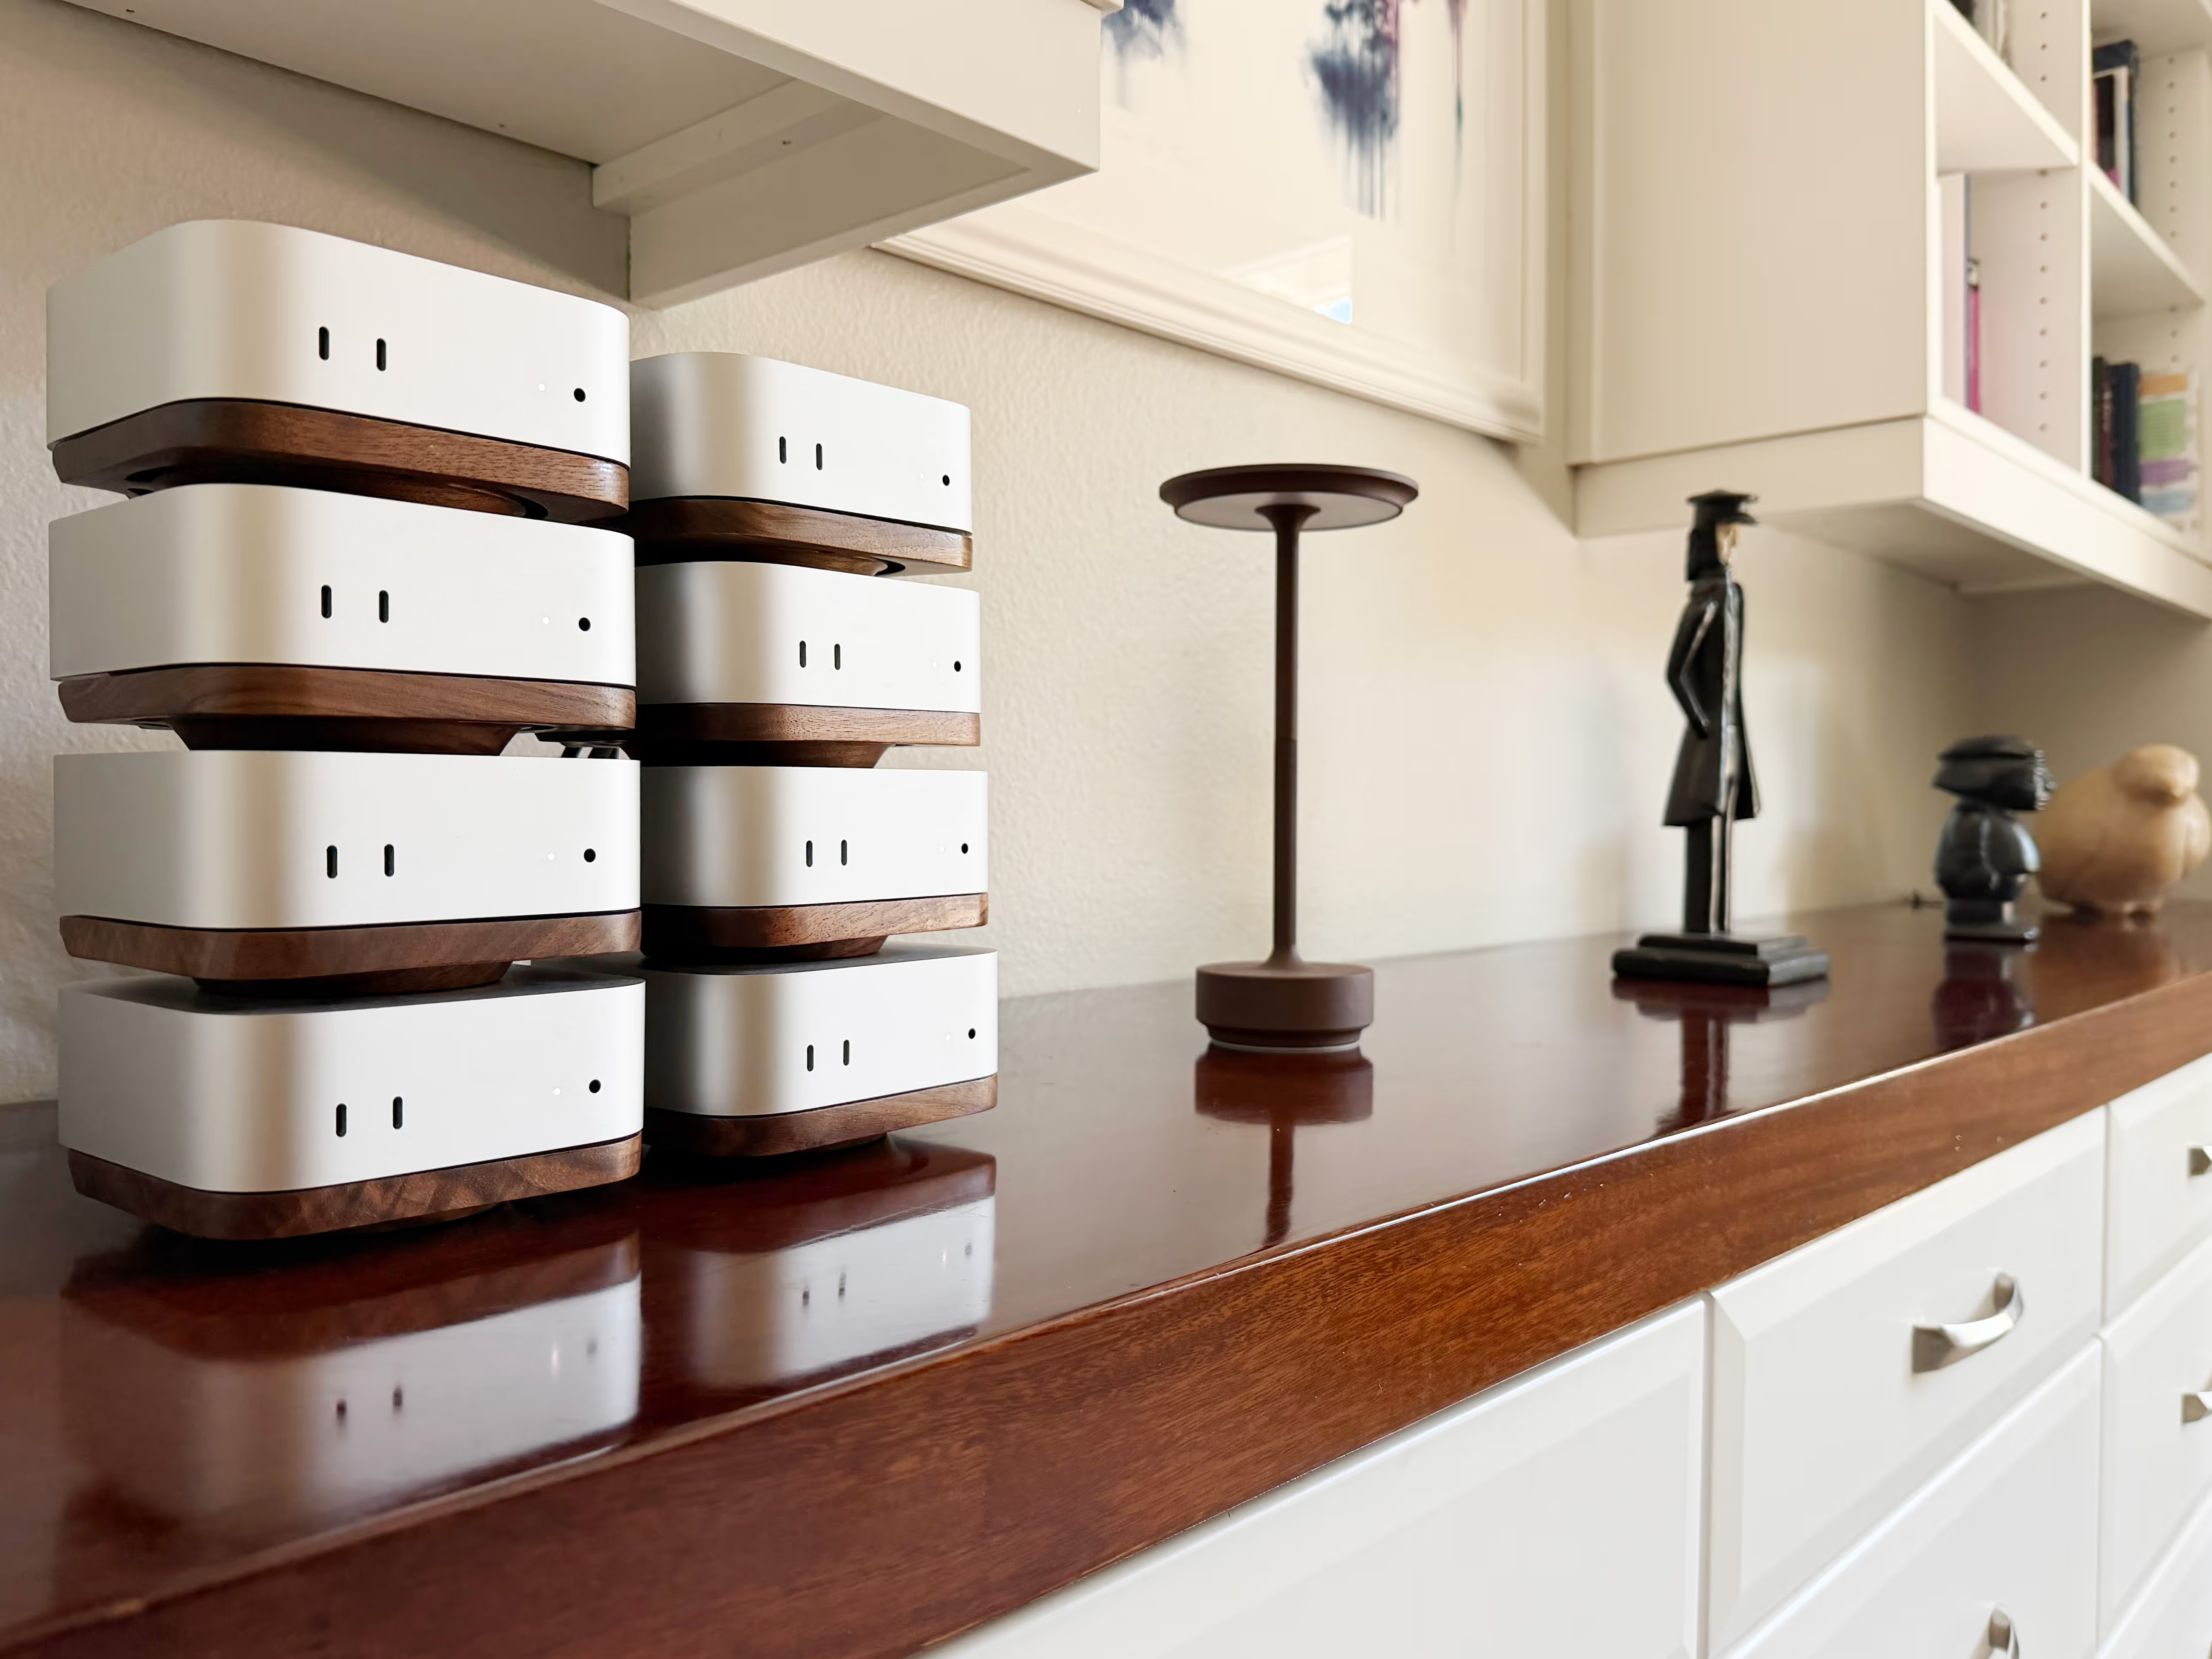
A local server cluster utilizing M4 and M4 Pro Mac minis to run AI workloads locally, reducing the need for costly cloud services.
Executive Summary
- The Challenge: Runaway cloud costs for high-volume AI speech transcription.
- The Solution: A localized, on-premise Apple silicon architecture.
- The Result: Reduced Google Cloud spend by $40,000 annually while maintaining ISO 27001 / SOC 2 compliance.
As the CTO of Yembo, where our AI platform processes data across 20+ countries, I am constantly auditing our tech stack for efficiency. I moved a major enterprise workload over to a local M4 Mac mini cluster to prove that scaling AI doesn't have to mean scaling your cloud bill. This move eliminated our reliance on Google Speech to Text. At the time, that service cost $0.016 per minute.
The Macs are using whisper.cpp, which runs on the Neural Engine and GPUs in the Apple silicon to transcribe calls locally. Transcription requests come in via SQS, and there's an autoscaler on Kubernetes in AWS that idles at zero, ready to pick up the work if there were to be an outage.
The performance is incredible: a single M4 Pro can keep up with 20 concurrent calls at 2x realtime. It's truly a testament to what these machines can do. However, speech transcription is just the beginning—only two of the eight machines in the cluster are dedicated to AI.
Speech Transcription
The original two AI services that started it all. Using whisper.cpp and Silero VAD, these dedicated nodes replaced Google Speech to Text.
GitHub Action runners
Paired with Biome, repatriating our CI/CD pipeline dropped our full-repo build and lint times from four minutes down to just 40 seconds.
CircleCI
Self-hosted runners specifically configured to accelerate native app builds, capitalizing on the performance leaps of Apple silicon vs x86.
Playwright Automated QA
Our heavy daily regression testing suite is executed via self-hosted GitHub Action runners, keeping the tests fast and avoiding expensive cloud execution time.
Architecture & Specs
- M4 Pro Mac minis handling local AI inference
- whisper.cpp + Silero VAD for transcription
- SQS for request queuing
- AWS Kubernetes autoscaler (idling at zero) for fallback
- Handles 20 concurrent calls at 2x realtime per machine
Enterprise Compliance
My company is ISO 27001:2022 and SOC 2 compliant, so getting the details right to be able to launch this was a bit of a project. The cluster adheres to strict security and compliance requirements while keeping inference localized.
The Apple silicon advantage: unified memory for local LLMs
Running large language models in the cloud usually requires renting expensive enterprise-grade GPUs with dedicated VRAM. The M4 and M4 Pro Mac minis change that math with their Unified Memory Architecture. By sharing one large pool of high-bandwidth memory between the CPU and the GPU, a single M4 Mac mini can load and run models that would otherwise fail on consumer hardware.
| Hardware Configuration | Model & Quantization | Framework | Performance |
|---|---|---|---|
| M4 Pro with 64 GB Unified Memory | Llama 3 8B quantized to Q8_0 | llama.cpp and Ollama | 58 tokens per second |
| M4 Pro with 64 GB Unified Memory | Llama 3 70B quantized to Q4_K_M | llama.cpp and Ollama | 14 tokens per second |
| Base M4 with 24GB Unified Memory | Llama 3 8B quantized to Q4_K_M | MLX Framework | 42 tokens per second |
To size a configuration yourself, the Apple silicon local LLM memory and speed calculator estimates required unified memory, prefill speed, and generation tokens per second for every chip from M1 to M6.
This cluster was built on M4 and M4 Pro hardware, and the architecture has outlived the chips in it. If you are specifying a build today, the decision has moved to whether you buy one M5 Ultra Mac Studio, one M5 Pro Mac mini, or a swarm of M6 Mac minis, which is the memory bandwidth argument laid out in M5 Ultra vs. M5 Pro vs. M6 for local AI. The models have moved too: a 27B class coding model like Qwen 3.8 running locally under Ollama now does the work that justified a cloud API contract when this cluster went into service, and the full field of current options is weighed in the best local LLMs for agentic coding. Which runtime serves those weights turns out to matter too: benchmarking MLX against Ollama on identical weights put a 40 percent gap between them on one model and reversed it on another.
Building a private AI agent appliance
With the rapid rise of autonomous agent frameworks like OpenClaw and the Hermes Agent, the need for a highly secure, private runtime environment is critical. Deploying these agents locally on our M4 cluster prevents proprietary enterprise data, internal communications, and database schemas from being transmitted to third-party APIs.
Our cluster functions as a highly secure private AI appliance. Since all model inference is executed within our restricted local network perimeter, we eliminate external data transit entirely. This architecture allowed us to easily pass our rigorous ISO 27001:2022 and SOC 2 audits, showing that local AI can be both highly innovative and structurally compliant.
Why this matters for business leaders
AI doesn't have to mean runaway cloud bills. By strategically offloading specific, high-volume workloads like transcription to specialized, cost-effective on-premise hardware like Apple silicon, businesses can achieve massive ROI while maintaining enterprise-grade reliability and security compliance.
This is no longer a contrarian position. Sequoia Capital's guide to sovereign AI, Own Your Intelligence, makes the same case from the investor's side of the table: as open-weight models close the gap with frontier APIs, owning your intelligence layer protects margins, keeps proprietary data internal, and turns the model itself into product differentiation. The cluster on this page is what that strategy looks like as hardware on a shelf.
The enterprise side is moving the same way. In August 2026, Thomson Reuters launched Thomson, an in-house large language model, alongside an upgraded CoCounsel Legal platform, and Simply Wall St asked the obvious question: is Thomson Reuters building a defensible edge by owning its own legal AI? Their answer is that owning the model, rather than renting one, is what turns proprietary content into a moat competitors cannot rent their way around. Thomson Reuters runs that model with cloud partners rather than on hardware it owns, which is the part this series takes further: the strategic argument for owning the model is the same argument for owning the machine it runs on, and at Apple silicon prices that second step is now within reach of teams far smaller than Thomson Reuters.
Bring your AI strategy down to earth.
If you want a proven, actionable blueprint to manage cloud costs, optimize your hardware, and securely deploy enterprise AI without the hype, let's talk.
See AI Speaking ProgramsJoin the Local AI Group
Scaling localized AI workloads in enterprise and hyper-growth environments requires solving highly complex infrastructure, secure networking, and hardware optimization challenges at scale.
The Local AI Group is the premier global technical network designed exclusively for active senior engineering leaders, including Chief Technology Officers, VPs of Engineering, and Directors of Engineering at Fortune 500 companies and top-tier startups. Our invitation-only space connects leaders scaling production-grade local AI systems. We bypass commercial marketing hype to focus strictly on hardware topologies, private LLM clusters, enterprise security frameworks, and custom sandboxing alongside elite peers operating at the absolute top of the global technology sector.
Roundtable focus areas
- Direct exchange on physical cluster topologies, high-throughput GPU clusters, and enterprise server architecture
- Vetted blueprints for thermodynamic profiles, process orchestration, and private model deployment pipelines
- Hardened boundary defense frameworks for satisfying SOC 2, ISO 27001, and GDPR perimeters with repatriated infrastructure
I vet each application myself to ensure a high-signal environment of peer practitioners.
Apply to Join the Slack GroupSharing confidential or proprietary information is strictly forbidden. Participation is subject to the Terms of Use.
Building a Mac cluster for local AI
This article is part of an in-depth technical series detailing the creation of a localized Apple silicon server cluster for enterprise AI inference, covering Mac mini and Mac Studio hardware, local agent hosting, and agentic coding.
How we built an M4 Mac mini cluster to cut AI cloud spend by $40k/year
The business case and localized architecture that cut enterprise Google Cloud spend by $40,000 annually.
Local AI use cases: local vs. cloud AI architecture
The enterprise decision matrix mapping air-gapped compliance, agentic coding, robotics, batch execution, and offline operations to local Apple silicon or cloud APIs, plus the hybrid local-first framework.
M5 Ultra vs. M5 Pro vs. M6 for local AI
Whether to buy one 512GB M5 Ultra Mac Studio, one M5 Pro Mac mini, or a swarm of 2nm M6 Mac minis, with the memory bandwidth math that decides it.
How to build an M6 or M5 Pro Mac mini cluster
Step-by-step setup guide covering hardware configuration, base macOS setup, secure remote access, process management, and cloud fallbacks.
Run Qwen 3.8 on Apple silicon, without rate limits
Running Qwen3.8-27B locally with Ollama and Zoo Code, plus the Mac mini and Mac Studio memory bandwidth numbers that decide whether local agentic coding is usable.
Best local LLMs for agentic coding on Apple silicon
Qwen 3.8, Qwen3-Coder, Gemma 4, DeepSeek V4 Flash, and GLM-5.3 compared for agentic coding, with the memory math that matches each model to the Mac that runs it.
Local AI agent hosting on M6 and M5 Pro Mac minis
Configuring a secure, low-power private AI appliance for always-on autonomous agent workflows.
Local AI Security: ISO 27001:2022, SOC 2 & GDPR Compliance
Architecting a hardened physical perimeter to satisfy rigorous enterprise ISO 27001:2022 and SOC 2 audits, plus the GDPR case for keeping inference in-house.
MLX vs Ollama on Apple silicon, measured
Fifty-four benchmark runs on the same weights and matched quantization, showing where each engine wins and why the answer changes with the model.
What a fanless Mac sustains under load
Six ten-minute runs on an M5 MacBook Air measuring what throughput actually holds, why a median of three overstates it, and why mains power turned out slower than battery.
Community Discussions
The concept of using Apple silicon for localized AI infrastructure resonated strongly with the developer and self-hosting communities. You can read the original case studies and follow the deep-dive technical discussions here: